Test Automation Strategy: The Pyramid and Flaky-Test Discipline That Keeps Your Release Pipeline Trustworthy
Your release pipeline is green, your dashboard says 87% coverage, and yet a customer just found a bug in the checkout flow that no test caught. At the same time, your engineers have learned to re-run the build "just in case" because one in ten runs fails for no reason anyone can explain. At AEGONTECH LLC we meet this combination in almost every engagement: a large test suite that is simultaneously too weak to catch real defects and too noisy to trust. This article explains how to design a test automation strategy that fixes both problems.
Key Takeaways
- Test automation is an investment portfolio, not a coverage number. Spread effort across unit, integration and end-to-end tests according to cost and speed, not habit.
- Flaky tests are a trust problem before they are a quality problem. Google has reported that roughly 16% of its tests showed some level of flakiness; once engineers distrust red builds, real failures get ignored.
- The testing pyramid still works, but only if you enforce its shape. Many fast, small tests at the base; few slow, broad tests at the top.
- Measure the suite itself: pass-rate stability, feedback time and escaped defects tell you more than line coverage.
- Quarantine, fix, or delete. A flaky test left in the main pipeline is a tax paid on every commit.
What is a test automation strategy, and why does it matter?
A test automation strategy is a deliberate plan for which behaviors you verify automatically, at which level of the system, and how fast you need the answer. It matters because testing has a cost in engineering time, CI minutes and attention, and a poorly shaped suite makes every release slower without making it safer.
The business stakes are real. A frequently cited 2002 NIST study estimated that inadequate software testing infrastructure cost the US economy roughly $59.5 billion a year, and the underlying economics have not changed: a defect found in a developer's editor costs minutes, while the same defect found by a customer costs support time, trust and sometimes revenue. The DORA research program also ties delivery performance to automation: elite teams keep their change failure rate in the 0-15% range while deploying on demand, which is only possible when automated tests are fast and believable.
"A test suite is a decision-making tool. If your team cannot act on its result within ten minutes, it is documentation, not a safety net."
How should you shape the testing pyramid?
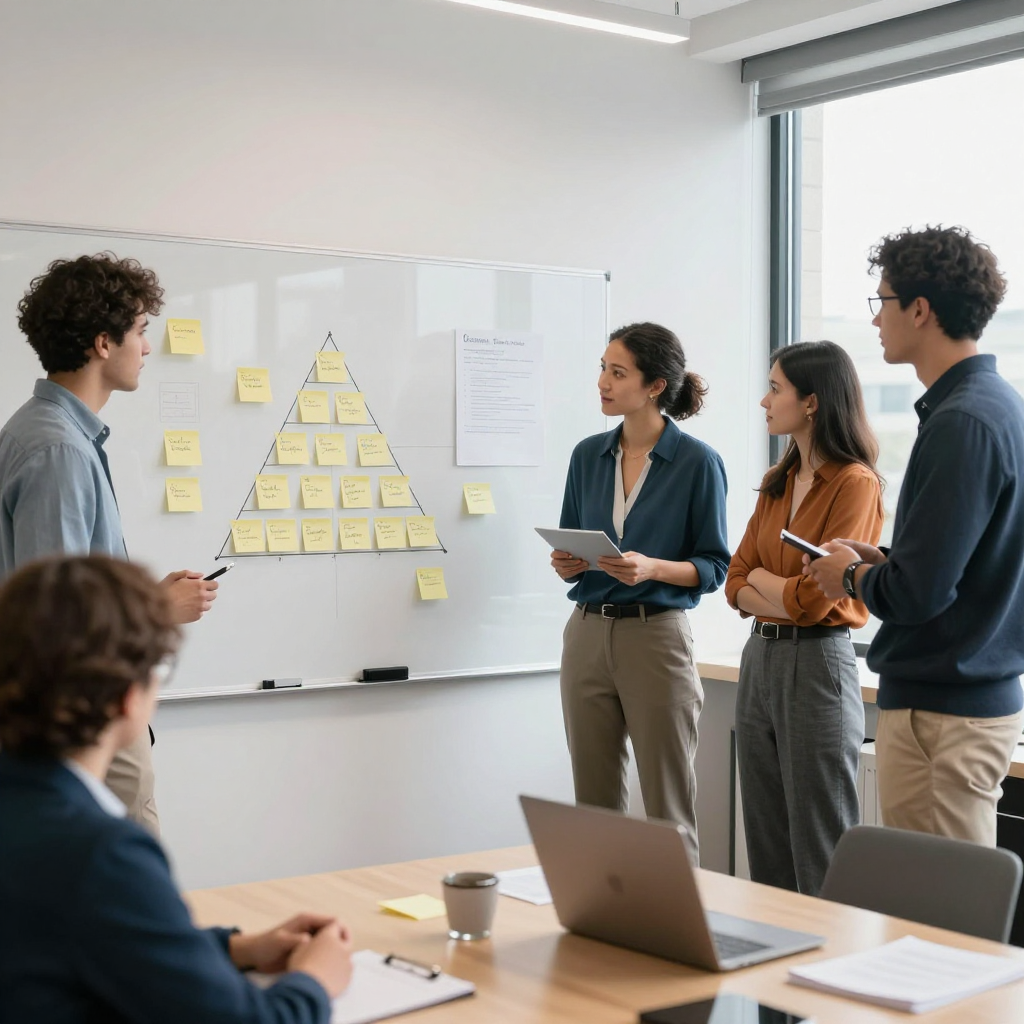
Shape your suite like a pyramid: a broad base of fast unit tests (tests that check one function or class in isolation), a middle layer of integration tests (tests that check several components, such as your code plus a real database, working together), and a thin top of end-to-end tests (tests that drive the whole application through its user interface or public API).
The reason is arithmetic. A unit test runs in milliseconds and fails in one obvious place. An end-to-end test may take thirty seconds, depend on a browser, a network and test data, and fail for a dozen unrelated reasons. A suite with 2,000 unit tests, 300 integration tests and 40 end-to-end tests finishes in minutes; invert those numbers and your pipeline takes an hour and fails at random.
A practical starting ratio we use at AEGONTECH is roughly 70% unit, 20% integration and 10% end-to-end by count, adjusted by risk. Payment flows, authentication and data migrations deserve disproportionate integration and end-to-end attention because failure there is expensive. A marketing page does not.
Why do flaky tests do so much damage?
A flaky test is a test that passes and fails on the same code without any change. They do outsized damage because they destroy the one property that makes automation valuable: a red build must mean something is wrong.
Google's engineering team has published that a large majority of the pass-to-fail transitions they observed in post-submit testing involved a flaky test rather than a real regression. Think about what that does to behavior. Engineers learn to retry, then to ignore, then to merge on red. The day a genuine regression arrives, it looks exactly like the noise everyone already tunes out.
The usual causes are predictable:
- Shared state: tests that depend on order or on data another test left behind.
- Timing assumptions: fixed sleeps and race conditions in asynchronous code, common in React and Node.js front ends.
- Uncontrolled dependencies: real clocks, random values, third-party APIs and network calls.
- Environment drift: a CI runner that differs from local machines in memory, CPU or time zone.
How do you fix a flaky test suite?
Fix flakiness by measuring it first, then quarantining offenders, then removing root causes. Do not start by asking engineers to "be more careful"; start with data.
- Measure. Have CI record per-test pass and fail history. Any test that fails and then passes on retry against the same commit is flaky by definition.
- Quarantine. Move flaky tests to a separate non-blocking job within a day of detection, with an owner and a deadline. The main pipeline must stay trustworthy.
- Diagnose. Replace sleeps with explicit waits on conditions, inject fake clocks and seeded random generators, isolate data per test (a fresh schema or transaction rolled back after each test works well with PostgreSQL), and stub external services.
- Decide. After two weeks, a quarantined test is either fixed or deleted. A test nobody trusts has negative value.
"Deleting a flaky test you will never fix is not lowering your standards. Keeping it is."
Vs: should you invest in end-to-end tests or integration tests?
Prefer integration tests for most business logic and reserve end-to-end tests for a small number of critical user journeys. Integration tests exercise real boundaries such as your service talking to a real database in a Docker container, so they catch the defects that mocks hide, but they avoid the browser, rendering and network layers that make end-to-end tests slow and brittle.
A good rule: if a behavior can be verified through an API call against a containerized dependency, do not verify it through a browser. Keep a handful of end-to-end "smoke" journeys, such as sign up, log in and pay, and run them on every release. For services that talk to each other, consumer-driven contract tests complement this approach by verifying agreements between teams without spinning up the whole system.
What should you measure instead of coverage?
Measure whether the suite helps you ship safely and quickly. Line coverage tells you which code ran during tests, not whether any assertion would catch a mistake there. A function can be 100% covered by a test that asserts nothing.
Track these instead:
- Feedback time: minutes from push to a trustworthy result. Aim for under ten for the main pull-request pipeline.
- Flake rate: the share of runs that fail and then pass on retry. Anything above 1-2% deserves attention.
- Escaped defects: bugs found in production per release, with the missing test type noted in each postmortem.
- Mutation score: the share of deliberately injected code changes your tests detect, a far better quality signal than coverage for critical modules.
- Change failure rate: a DORA metric that shows whether testing improvements reach customers.
How does AEGONTECH approach test automation on real projects?
We treat the suite as a product with its own backlog. On our own products, including Dolfy.ai, Dialable.world and Mimicall.app, small teams ship often, and that is only sustainable because the pull-request pipeline stays fast and trusted. Every new feature ships with tests at the lowest level that can prove it, and any test that flakes twice gets quarantined automatically.
When a client brings us an existing codebase, the first step is a two-week suite audit: run the tests fifty times on the same commit to find flakes, profile the slowest ten percent, map existing tests to the pyramid layers, and review the last six months of production incidents to see which test layer would have caught each one. The output is a short, ranked plan, not a rewrite. Teams typically recover several hours of engineering time per week just by removing the worst offenders.
Practical checklist for the next quarter
- Publish the pipeline's current flake rate and feedback time on a shared dashboard.
- Quarantine every known flaky test and assign an owner.
- Add a rule that a bug fix must include a regression test at the lowest viable level.
- Cap end-to-end tests at a number your team agrees on and review additions.
- Run the full suite nightly with random ordering to expose hidden dependencies.
- Review escaped defects monthly and adjust where new tests are added.
FAQ
How many tests is enough? There is no universal number. Enough means the team can refactor with confidence and escaped defects are rare and low severity. Add tests where risk is high rather than chasing a coverage target.
Should we automate everything? No. Exploratory testing by a thoughtful person finds usability and workflow problems automation cannot. Automate repeatable regression checks and keep humans for judgment.
Is test-driven development required? Not required, but writing the test first tends to produce smaller, more testable designs. Many teams adopt it for complex business logic and skip it for simple glue code.
How do we handle flaky tests we inherited? Measure, quarantine, then fix or delete on a deadline. Never leave them in the blocking pipeline while you "get to them later."
Conclusion
A good test automation strategy is less about how many tests you own and more about whether anyone believes them. Shape the pyramid, hold flakiness to account, and measure the suite's real outcomes: speed, stability and fewer escaped defects. If your pipeline is slow, noisy or quietly ignored, the team at AEGONTECH LLC can audit it and give you a prioritized plan. Book a consultation at aegontech.dev and we will show you where your suite is spending your engineers' time.