API Gateway Architecture: The Traffic Control Layer That Decides Whether Your Microservices Scale or Collapse
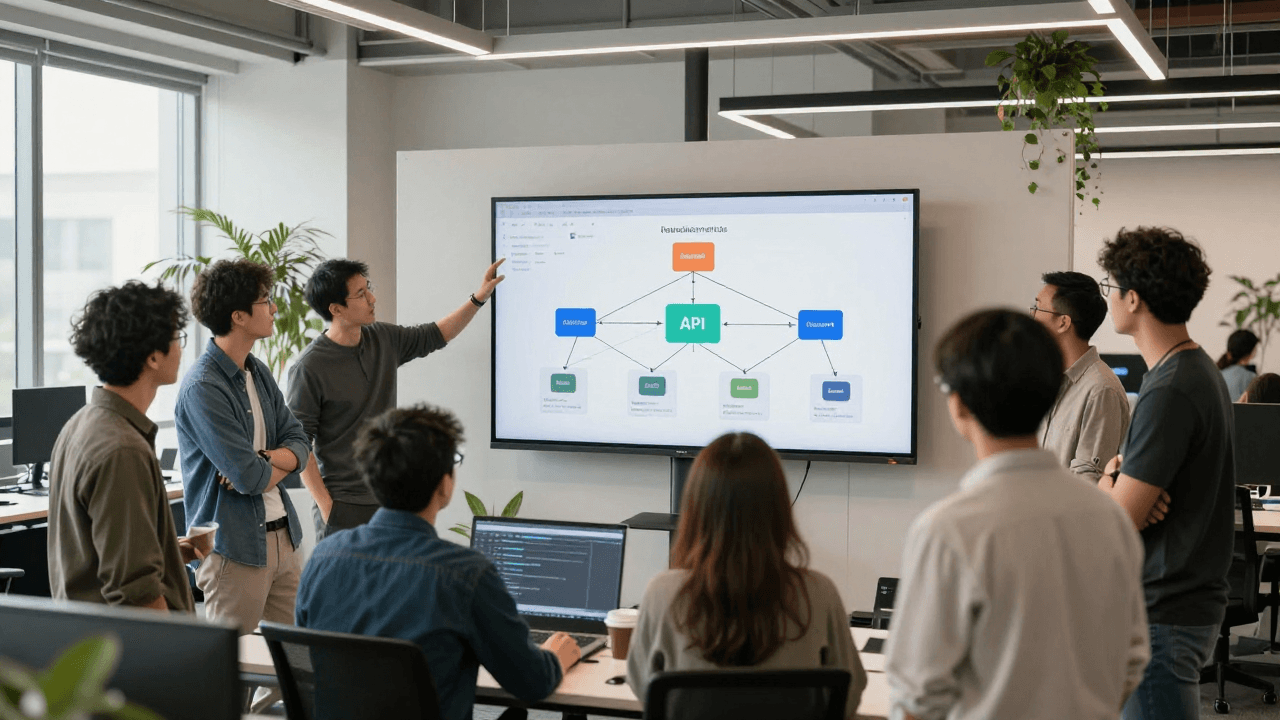
Every growing engineering organization eventually hits the same wall: what started as three or four services calling each other directly turns into a dozen, then thirty, and suddenly nobody can say with confidence which client talks to which backend, or who is responsible for authenticating a request before it reaches a database. At AEGONTECH LLC, we've walked client teams through this exact inflection point enough times to recognize it on sight — and the fix is rarely "write more code." It's usually an architectural decision that should have been made months earlier: introducing a proper API gateway.
Key Takeaways
- An API gateway is a single, deliberate entry point for external traffic — not a bolt-on proxy you add after the third production incident.
- The real choice isn't "gateway or no gateway," it's which pattern — centralized gateway, service mesh, or backend-for-frontend (BFF) — fits your team's actual topology.
- Authentication, rate limiting, and request aggregation belong at the edge, not duplicated inside every service.
- A managed gateway (AWS API Gateway, Azure API Management, Kong, Google Cloud's Apigee) buys speed; a self-hosted one buys control — the right answer depends on your compliance posture and team size, not on which one is trendier.
- Migrating to a gateway without downtime is a phased, traffic-shifted process, not a weekend cutover.
What Is an API Gateway, and Why Do Growing Systems Need One?
An API gateway is a single managed entry point that sits between external clients — web apps, mobile apps, third-party integrators — and your internal services, handling routing, authentication, rate limiting, and often response aggregation before a request ever reaches application code. Without one, each service reimplements its own authentication check, its own throttling logic, its own CORS handling, and those implementations drift apart within a year. We've seen engineering teams discover, mid-incident, that two services validate JSON Web Tokens (JWTs) differently — one checks expiry with a five-minute grace window, the other doesn't — and that gap becomes the exploit an attacker finds first.
This isn't a hypothetical. In client engagements, AEGONTECH's engineers have found that teams running more than a dozen internal services without a unified gateway layer spend roughly 20-30% more engineering time on cross-cutting concerns like auth debugging and CORS misconfiguration than teams that centralized those concerns early. That's not wasted code — it's wasted judgment, repeated a dozen times over.
A well-designed gateway also gives you a single place to answer the question every CTO eventually gets asked in a board meeting: "if this endpoint gets hit ten times harder tomorrow, what happens?" With a gateway enforcing rate limiting and circuit breaking at the edge, the honest answer becomes "the gateway absorbs it and degrades gracefully" instead of "we're not sure."
API Gateway vs Service Mesh vs Backend-for-Frontend — Which Pattern Fits?
This is where most teams get the decision wrong, not because they pick a bad option, but because they treat it as one choice when it's really three overlapping ones.
A centralized API gateway (think Kong, AWS API Gateway, or Azure API Management) governs north-south traffic — everything coming in from outside your cluster. It's the right default for most product teams, including the kind of B2B and consumer products AEGONTECH builds, like Dolfy.ai and Mimicall.app, where the primary concern is client-to-backend traffic, not service-to-service chatter.
A service mesh (Istio, Linkerd) governs east-west traffic — service-to-service calls inside your cluster — adding mutual TLS, retries, and observability between internal services. It solves a different problem and is usually overkill below 15-20 internal services; we've watched teams adopt Istio prematurely and spend more time debugging the mesh's own sidecar proxies than they saved on service-to-service reliability.
A backend-for-frontend (BFF) is a thin aggregation layer built specifically for one client type — a mobile BFF that batches three backend calls into one response so a phone on a weak connection makes one round trip instead of three. Video and real-time products, like Maximus IPTV Player or a WebRTC-heavy calling product, benefit enormously from this pattern because network round trips are the actual user-facing cost.
The honest comparison: a gateway is about control at the edge, a mesh is about reliability in the middle, and a BFF is about shaping data for one specific client. Most teams need the first, some eventually need the second, and a growing number benefit from a thin version of the third layered on top of the gateway rather than instead of it.
What Problems Does a Gateway Actually Solve in Production?
Three, consistently, across nearly every engagement:
Authentication and authorization sprawl. Instead of every service independently validating tokens, the gateway validates once and passes a trusted identity downstream — often as a signed internal header. This is the single biggest reduction in attack surface a mid-sized engineering org can make in a quarter, and it's a control that shows up directly in a SOC 2 audit as evidence of consistent access control enforcement.
Rate limiting and abuse protection. Without a gateway, rate limiting for a service in Node.js and rate limiting for one in Python inevitably use different libraries, different Redis key formats, and different definitions of "too many requests." Centralizing it at the edge means one policy, one dashboard, one incident response runbook.
Request aggregation and protocol translation. A gateway can expose a clean REST or GraphQL surface to clients while internally routing to a mix of REST, gRPC, and event-driven services — letting backend teams evolve their internal protocols without breaking every client integration.
"A gateway that only does routing is a load balancer wearing a costume," is a line one of our senior architects uses with clients who want to build the bare minimum. The value is in the authentication, observability, and rate-limiting layers stacked on top of routing — not routing itself.
How Do You Choose Between a Managed Gateway and a Self-Hosted One?
This decision usually comes down to three factors: compliance requirements, team size, and how much you're already committed to a specific cloud.
A managed gateway — AWS API Gateway, Azure API Management, or Apigee on GCP — gets you to production in days, not weeks, with built-in scaling, TLS termination, and usage analytics. For a team of five to fifteen engineers, that speed is usually worth the tradeoff in configuration flexibility. It's the path AEGONTECH recommends for most early-stage and growth-stage clients, particularly ones already deployed on AWS or Azure who don't want a new operational surface to own.
A self-hosted gateway — Kong, Traefik, or an Nginx-based custom layer running in Kubernetes via Docker containers — gives you full control over plugin behavior, custom authentication schemes, and data residency, which matters enormously for regulated industries or companies pursuing SOC 2 Type II or HIPAA compliance where auditors want to see exactly how a control is implemented, not just that a vendor claims it exists. The tradeoff is real: you now own patching, scaling, and high availability for a piece of infrastructure that, if it goes down, takes your entire API surface with it.
Our rule of thumb after enough of these migrations: if your compliance team has ever used the phrase "we need to be able to demonstrate," lean self-hosted or a managed gateway with strong audit logging. If your compliance burden is standard SaaS terms-of-service territory, a managed gateway is very likely the right call, and the time saved is better spent on product work.
What Does a Gateway Migration Look Like Without Downtime?
Retrofitting a gateway onto a live system is one of the more delicate migrations in software engineering, precisely because the gateway sits in the critical path of every request. The pattern that works, consistently, across AEGONTECH client engagements:
- Shadow mode first. Route a copy of production traffic through the new gateway without serving its responses to real users, and diff the outputs against the existing path. This catches serialization mismatches and auth edge cases before they're customer-facing.
- Canary a single low-risk endpoint. Pick a read-only, low-traffic route and cut it over first, with monitoring and a one-click rollback ready.
- Migrate by traffic percentage, not by endpoint count. Move 5%, then 25%, then 50% of traffic through the gateway using weighted routing, watching error rates and p99 latency at each step, rather than declaring victory after moving "most" endpoints.
- Decommission the old path last, deliberately. Keep the legacy direct-access path alive — but locked down — for at least one full release cycle after full cutover, in case a forgotten internal script or partner integration still calls it directly.
Teams that skip the shadow-mode step are, in our experience, roughly twice as likely to have a rollback-triggering incident in the first 48 hours after cutover. The extra week of shadow traffic comparison is cheap insurance against a very expensive rollback.
Frequently Asked Questions
Does a small startup with three services need an API gateway? Usually not yet — but the threshold is lower than most teams assume. If you have more than one client type (web and mobile, or a public API for partners) hitting the same three services, a lightweight gateway is worth introducing early, because retrofitting one later is strictly harder than building with one from day one.
Can an API gateway become a single point of failure? Yes, if deployed carelessly. The fix is treating the gateway itself as a highly available, horizontally scaled service — with health checks, multiple availability zones, and its own circuit breakers — not as a single box you're relieved to finally stop thinking about.
How is an API gateway different from a load balancer? A load balancer distributes traffic across instances of the same service. A gateway does that plus authentication, rate limiting, request transformation, and routing across different services — it's application-aware in a way a plain load balancer isn't.
Does adopting a gateway lock us into a specific cloud vendor? A managed, cloud-native gateway does add some lock-in risk — it's a legitimate vendor lock-in question worth raising with your architecture team before committing. Self-hosted options like Kong avoid that specific risk while trading it for operational ownership, which is exactly the kind of build-vs-buy tradeoff worth walking through with an experienced partner before you commit engineering quarters to either path.
Getting the Gateway Layer Right the First Time
The teams that get the most value from an API gateway are the ones who treat it as an architectural decision worth deliberate planning, not a library they can npm install on a Friday afternoon. Get the pattern right — gateway, mesh, BFF, or some deliberate combination — and authentication, rate limiting, and observability stop being thirty separate implementations and become one well-tested layer everyone can reason about.
This is exactly the kind of infrastructure decision where an outside perspective helps, because the teams closest to the code are often too close to see that the real problem isn't which library to pick, it's which pattern to commit to. If your engineering organization is approaching this inflection point — or living with the consequences of having crossed it without a plan — AEGONTECH LLC works with engineering teams and technical leaders on exactly this kind of architecture decision, from initial assessment through a zero-downtime migration. Reach out through aegontech.dev to talk through where your system actually stands today.